Gradient Boosting Decision Trees (GBDT) are among the commonly used algorithms built on decision trees. Decision trees are one of the simplest approaches to predictive modeling to explain.
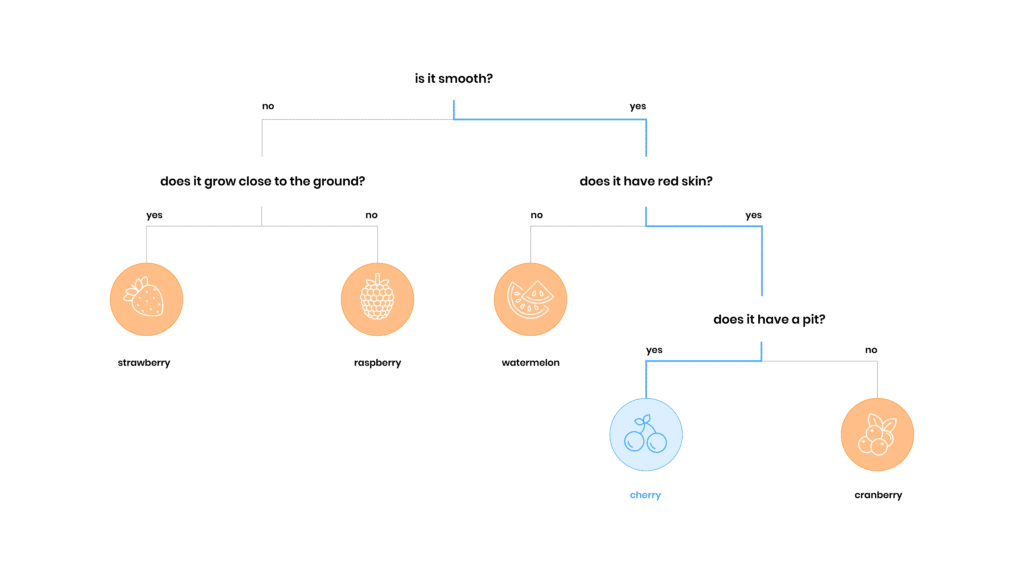
By asking a series of yes/no questions about the input item, they can assign it to a particular category or leaf. Each question is like a crossroads: you can go left or right. You start from the top of the tree, called the root, and subsequently choose the left or right branch until you reach the bottom.
The process is presented in the picture below. Blue line shows what happens when a decision tree that can classify red fruits sees a cherry. Starting from the root, the tree asks its questions and determines that the object it analyzes is smooth, has red skin and a pit. This is enough for the algorithm to decide that it most likely is a cherry.
What Are Gradient Boosting Decision Trees?
- A way of learning the structure of trees ensemble
- A powerful, easy to try out model that can give very good results out of the box
- A model with built-in feature selection
Side note: the example presented in the picture is a classification use case (determining the type of an object), but trees can also be used for regression when we expect a numerical answer instead of a category. A popular tree structure used for this is CART (Classification and Regression Tree).
How Gradient Boosting Decision Trees Work
A single tree is useful because it’s easy to understand. However, the best results are usually obtained using tree ensembles. This means having multiple trees modeling the same problem. Each of them is then asked what it “thinks” about the input. The trees “vote” on the correct answer. If the majority of trees say that an object is a tomato, we take “tomato” as the answer to the whole model. Now the challenge is: how to choose (or, in ML terms, learn) the structure of all those trees? Of course, there are many ways. One of them is called gradient boosting decision trees (GBDT). Gradient boosting decision trees is a method of training ensemble tree models in an iterative fashion. It uses a clever trick to express the decision tree as a differentiable mathematical function. This allows us to use numerical optimization methods to construct the model by adding the best trees to the ensemble one by one.
Advantages and Usage of Gradient Boosting Models
The great advantage of GBDTs is the fact that they require very little data preparation. This makes them a very useful benchmark – we can effortlessly apply them to almost any problem, even when we don’t understand our data very well. All that is needed is a dataset where the outcome is described by a vector of variables (they don’t even have to be numerical!).
Methods from the area of random trees turned out to be a game-changer in one of my projects. I used this approach to increase the efficiency of the food delivery the company by 10%.
Tomasz Juszczyszyn, Data scientist, Stermedia
What Can We Use Gradient Boosting Decision Trees For?
- Preparing a good benchmark model for our problem
- Predicting an outcome using variables with different characteristics
- Automatically choosing which features are the most important
- Handling arbitrary loss function
Gradient boosting decision trees have built-in feature selection, so we don’t have to worry about not knowing which variables are the most helpful in a particular use case. The algorithm will automatically find the best way to use the information we provide as input. More advanced users will be happy to know that GBDTs can handle arbitrary loss functions. This means we are free to decide how we measure the quality of the answers given by the trees.
There is no, one, be-all-end-all implementation of GBDTs, but in Stermedia we mostly use XGBoost, LightGBM and CatBoost. All three are written in Python and can give very good results out-of-the-box. We recommend you try them and see what they tell you about your data!
About the Author
Maciej Pawlikowski – Data Scientist. He holds a degree in both math and computer science. Interested mostly in natural language processing. Maciej also worked successfully in time series forecasting. Big enthusiast of optimization and code style. Always on the hunt for more efficient and convenient tools for data science and coding.
Next steps & further reading
If you want to explore how Gradient Boosting Decision Trees can support predictive modeling for your business, the best starting point is a small, controlled pilot using real data and a clearly defined business problem.
At Stermedia, we help organizations apply machine learning to real business challenges — from data analysis and model selection to production deployment.
Want to discuss your project? Contact our AI team.
Continue reading:
- Machine Learning for Food Delivery Efficiency – a real-world Stermedia case study showing how Gradient Boosting Decision Trees helped increase accepted delivery orders by 10%.
- AI Demand Forecasting in Pharma Supply Chains – how Stermedia applied machine learning techniques, including gradient-boosting models such as XGBoost, to pharmaceutical demand forecasting.
- Predictive Analytics in Business: Turning Data Into Foresight – how businesses use predictive models and historical data to anticipate outcomes, manage risks, and improve operational decisions.
Are you inspired?
Let’s talk about your idea.
Let’s talk